Welcome to Issue #46 of TAIS, where every Friday we spotlight visionary changemakers reshaping Africa’s tech, data, and AI landscape, one breakthrough at a time.
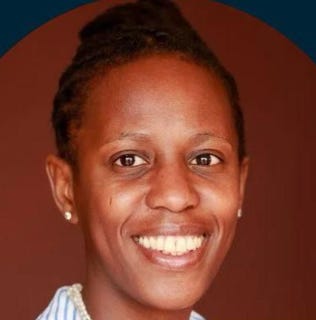
In today’s issue, we spotlight Prof. Mpho Primus, a South African computational linguist and AI researcher whose work sits at the intersection of linguistic theory and technological design, where African languages are either recognized as sophisticated knowledge systems in their own right or flattened into templates built for other tongues.
Her work moves between academic research on tone-labeling algorithms for Sesotho, digital transformation strategy through Primus Tech Hub, and policy advisory on governance frameworks that ask foundational questions: Who is represented? Whose values guide this system? What kind of future are we coding?
Professor Mpho Primus| NRF-Rated Computer Scientist | African NLP | AI Strategy & Governance
This conversation starts from a technical challenge “how do you build AI that understands languages where tone carries meaning, where social relationships shape syntax, where identity emerges relationally rather than individually?” But it doesn’t stay technical for long. It opens onto questions about what happens when mainstream models are trained without the linguistic theory required to interpret African languages on their own terms. When language technologies treat African languages as peripheral rather than foundational to digital inclusion. When AI deployment becomes something imposed on communities rather than shaped with them.
Along the way, Prof. Primus talks about the epistemic gap at the heart of current systems, about why you cannot automate inefficiency, about the difference between retrofitting African languages into existing architectures and designing algorithms from the ground up, about Ubuntu as both philosophical framework and practical governance tool, and about what changes when you shift from AI built for Africa to AI built from Africa.
What emerges from this conversation is beyond advocacy for multilingual AI. It’s a vision of technology grounded in African linguistic structures, ethics, and ways of knowing, where language stops being a barrier to digital access and becomes a foundation for equity, trust, and full participation in shaping what AI becomes.
Q: Your career sits at the intersection of language and technology. What first sparked your curiosity about African languages in AI?
A: My curiosity began during my undergraduate studies, when one of my Computer Science lecturers encouraged me to combine Computer Science with Linguistics through a new programme.
This path also opened the door for me to join the Human Language Technology Group at the Meraka Institute (CSIR) as a summer vacation student. Working alongside early pioneers of language technology in South Africa, I saw both the enormous potential of AI and the stark inequities in how our languages were represented. Even where tools existed, they rarely captured the full linguistic richness of African languages, especially tone, which is central to meaning in languages like Sesotho.
This gap ignited a lifelong commitment. It shaped my work from the very beginning, including early research where I developed a tone-labelling algorithm for Sesotho to show that our languages are not outliers to be squeezed into existing systems, but sophisticated knowledge structures in their own right. As a native Sesotho speaker, the work felt both personal and necessary: if AI is to serve African societies, it must first learn to understand our languages in their richness and fullness.
Q: You’ve built a body of work showing that linguistic theory is essential to NLP. What do current AI systems still misunderstand about African languages?
A: At the heart of these misunderstandings is an epistemic gap. Many AI systems are trained without the linguistic theory required to interpret African languages on their own terms, and this limitation is evident across mainstream models. My work argues that there is no NLP without the L: if systems do not grasp the internal logic, structure, and meaning-making processes of our languages, they cannot represent them fairly or accurately.
Ultimately, AI continues to underestimate the sophistication of African linguistic systems. These languages are not edge cases; they are complex, relational, and deeply embedded knowledge traditions. Until models are trained with linguistic theory that honours this complexity, African languages will continue to be flattened, mistranslated, or erased within the computational layers that shape global AI.
Editorial commentary: Many systems appear to work because they perform fluency well enough to pass casual inspection. They generate text that looks right, sounds right, and moves smoothly across familiar linguistic terrain. That success has encouraged the quiet assumption that meaning itself has been captured.
Prof. Primus’s work unsettles that assumption. Languages like Sesotho make visible something that English-centric NLP can afford to ignore for longer: meaning is not always carried where models expect it to be. Tone is not an accessory layered on top of words; it is part of the word. Shift it, and meaning shifts with it. Remove it, and the sentence may still look grammatical while saying something else entirely. The model keeps speaking, but it no longer knows what it is saying.
This is where the problem stops being one of representation and becomes one of epistemology. Systems optimised for statistical plausibility are rewarded for sounding right rather than for understanding how meaning is constructed. In that regime, languages whose logic does not align neatly with Indo-European assumptions do more than suffer neglect. They reveal the limits of the approach itself.
Prof. Primus’s insistence that there is “no NLP without the L” is therefore not a plea for inclusion. It is a methodological correction. Linguistic theory is not an optional layer to be added once scale is achieved but the very thing that tells the system where meaning actually lives. Without it, models confuse surface regularities for structure and coherence for comprehension.
The danger is that this confusion travels. Once systems that misunderstand language are embedded into search, education, public services, or governance, they begin to shape access to knowledge and opportunity while carrying their misunderstandings forward. The harm is subtle, cumulative, and difficult to trace, precisely because the outputs remain fluent.
Ubuntu as Linguistic Theory and Governance Framework
Q: Many people see language technology as purely technical. What cultural or social dimensions do you think are often overlooked?
A: Language is inseparable from social relationships, identity, and context. Meaning is co-constructed through interaction, not just encoded in words. This sits in tension with how most language models are trained. They learn from de-contextualised text, stripped of tone, social cues, and relational intention. As a result, models can generate fluent sentences while still misunderstanding what the speaker is doing whether signalling respect, expressing solidarity, or negotiating identity.
Q: Ethics is central to your approach. How do you define ethical AI in the context of African languages and cultures?
A: For me, ethical AI begins with the understanding that language is not just a medium of communication, it is a carrier of identity, history, and worldview. When AI systems fail to recognise African languages, they fail to recognise the people who speak them. Ethical AI therefore requires systems that can meaningfully engage with our linguistic diversity rather than treating our languages as peripheral or optional.
An Ubuntu-centred approach strengthens this perspective by offering a relational theory of meaning and personhood. Ubuntu positions human identity as emergent from social interaction I am because we are which aligns with well-established linguistic and cognitive science insights that meaning is co-constructed, context-dependent, and distributed across relationships. In an AI context, this requires systems that account for pragmatics, social cues, cultural norms, and interactional intent rather than relying solely on de-contextualised text. Ethical AI in Africa must therefore be designed with models that reflect how people actually communicate, reason, and relate to one another within real social environments.
In my work — whether through research, policy advisory, or digital transformation projects — I emphasise that ethical AI is not achieved by technical fixes alone. It requires community participation, transparent governance, and local ownership of data and capability. It requires imagining AI not as a tool imposed on society, but as an ecosystem that is shaped with and for the people who use it.
Editorial commentary: Prof. Primus’ work reaches beyond questions of representation and unsettles the quiet assumption that language can be extracted from social life without consequence. Once language models enter education, public services, or governance, that assumption doesn’t remain theoretical. It settles into infrastructure. Some forms of speech move through these systems easily. Others vanish without error messages.
What becomes visible is that language technology already operates as a form of governance. Not through explicit regulation, but through legibility. Systems decide which kinds of meaning are processable and which are not. When models are trained on de-contextualised text, stripped of tone, relational cues, and social intent, they privilege a particular way of speaking and, with it, a particular way of being understood. Languages that depend on context are not simply harder to model. In environments that reward isolation, abstraction, and individual utterance they are structurally disadvantaged.
This is where Ubuntu enters less as philosophy than as theory. If meaning is produced between people rather than contained inside sentences, then systems built to treat language as self-contained units are misaligned from the start. They do not fail intermittently. They perform well against the wrong objective, optimising output in settings where interaction is the point.
The Layered Architecture of Exclusion
Q: What barriers, technical, institutional, or societal still prevent African languages from being fully integrated into mainstream AI systems?
A: The barriers are layered. Technically, many of the models we rely on were never designed with African languages in mind. When we try to fine-tune these architectures for African languages, we are essentially forcing systems into frameworks that cannot represent their structure. Without algorithms built for these languages — and not just adapted to them — accuracy and fidelity will always be limited.
Institutionally, the gaps begin long before AI development. Many African languages are still under-documented; some lack large corpora, modern dictionaries, or up-to-date linguistic descriptions. Universities often do not offer the linguistic training needed to support advanced NLP work, and research funding tends to prioritise other fields. As a result, the capacity to build language technologies is uneven, and much of the intellectual and technical ownership remains outside the continent.
Societally, the biggest barrier is the perception that African languages are optional or secondary in digital innovation. This mindset influences policy priorities, procurement decisions, and even how people imagine the future of technology. When language is treated as a cultural artefact instead of a foundation for digital inclusion, it becomes easier to justify systems that exclude the majority of speakers.
These barriers reinforce one another: technical limitations shape institutional choices, which then shape societal expectations. Breaking this cycle requires investment in linguistic research, language-specific model design, community-driven datasets, and policies that treat African languages as essential infrastructure for digital transformation. Only then can they be fully integrated into mainstream AI systems.
Editorial commentary: What keeps African languages from settling at the centre of mainstream AI is less a single blockage than a pattern that repeats across layers. Systems are designed elsewhere, with assumptions baked in about what language looks like and how it behaves. Documentation and linguistic resources arrive unevenly or not at all, which limits what can be built locally. Those limits then travel upward into policy, procurement, and institutional planning, where they are treated less as design choices than as unavoidable constraints.
Over time, something quieter takes hold. African languages begin to register as optional to digital innovation rather than essential to it. Once that idea settles, underinvestment feels rational, adaptation becomes the default response, and exclusion no longer needs to be argued for. It simply becomes the background condition against which systems are judged “good enough.”
Prof. Primus’s account brings into focus how technical architecture, institutional capacity, and social perception end up reinforcing one another, not through explicit intent, but through alignment. The marginal position of African languages is not maintained by one decision, but by many small ones that point in the same direction.
From Retrofitting to Redesigning
Q: You’ve argued that AI can only be truly inclusive if it recognises African linguistic diversity. What would a genuinely multilingual AI ecosystem look like in practice?
A: A genuinely multilingual AI ecosystem begins with recognising that African languages are not technical obstacles but rich, structured systems that deserve to be modelled on their own terms. That means designing algorithms and models from the ground up, rather than fine-tuning architectures that were never built with these linguistic realities in mind. When we start from our own structures, instead of retrofitting them into someone else’s template, the technology shifts in both form and purpose.
It also requires investment in infrastructure: open and representative datasets, transparent governance frameworks, language-inclusive policy, and meaningful community participation in how models are trained, evaluated, and deployed. Multilingual AI must be locally owned, ethically governed, and aligned with national digital transformation priorities.
When these elements come together, language stops being a barrier to digital access and becomes a foundation for equity, trust, and full participation in the digital economy.
Editorial community: Long before questions of scale or access appear, systems have already made choices about what language is supposed to look like, how meaning should behave, and where complexity is allowed to live. Those choices rarely announce themselves. They settle early, inside architectures, training assumptions, evaluation benchmarks, and ideas of what counts as a “well-formed” input.
This is where Prof. Primus’s insistence on redesign rather than retrofit makes sense. Retrofitting accepts those early decisions as fixed and works around them. Redesign questions them. It treats African languages as systems capable of shaping the template itself. Grammar, tone, and relational meaning stop being inconveniences and begin to function as organising principles.
Once language is allowed to influence structure rather than merely populate it, multilingual AI stops looking like an expansion problem and starts to look like an authorship problem. Decisions about models, datasets, and governance no longer sit upstream from language; they are made with language in the room. This results in a system whose assumptions are no longer anchored to a single linguistic worldview.
You Cannot Automate Inefficiency
Q: You work both in academia and through Primus Tech Hub. How do you balance scientific research with real-world digital transformation work?
A: For me, the two are inseparable. My academic research gives me the depth and rigour to understand AI as a scientific field, how models learn, where they fail, and what responsible deployment looks like. My work through Primus Tech Hub shows me how these insights must inform digital transformation strategies and initiatives that actually serve people and institutions. I move constantly between theory and implementation: research helps me ask sharper technical questions, while real-world transformation work reveals the gaps that need solving, whether in data, policy, governance, infrastructure, or organisational readiness.
Balancing the two is not about splitting my time; it’s about aligning my purpose. Research builds knowledge. Digital transformation applies that knowledge to modernise systems, strengthen capability, and improve how organisations deliver value and it reinforces the need for frameworks that are locally developed, contextually grounded, and aligned with what our organisations genuinely require. Together, these domains allow me to advocate for AI that is scientifically rigorous, ethically grounded, and practical enough to create meaningful and sustainable impact.
Q: Many organisations approach AI and data strategy as a purely technological challenge. From your experience, what human or organisational shifts need to happen first?
A: The biggest shift is recognising that AI is not a technology project, it is a change project. The organisations that struggle most are the ones that try to “install” AI on top of old ways of working. The ones that succeed are those that start by shifting mindsets, culture, and capability long before selecting a tool.
The first shift is clarity of purpose. At times, organisation want AI-powered technologies because it feels modern, but they haven’t articulated what problem they are solving or how success will be measured. Without clarity, the technology becomes a distraction rather than a solution.
The second is building internal capability and confidence. AI requires people who understand data, governance, process design, and ethics, not just engineers. When staff don’t feel equipped, they either resist the change or rely entirely on vendors, which creates long-term risk. Organisations need to invest in literacy, training, and cross-functional teams that can bridge technical and operational worlds.
Editorial commentary: In many institutions, AI arrives as a procurement decision long before it becomes an organisational one. A tool gets selected, a pilot begins, expectations rise. Only later does it become clear that the surrounding processes (how data is recorded, how decisions move, who understands what) were never designed to carry what the tool is supposed to do. The result isn’t failure so much as friction that keeps repeating.
What Prof. Primus describes, moving between academic research and transformation work, is the slow work of making organisations ready to use what they claim to want. Research clarifies how systems function and where they break; implementation reveals how those insights land inside institutions with habits, constraints, and uneven capacity. The two feed each other. Questions sharpen on one side and get tested on the other.
The pattern underneath it all is familiar. Automation tends to amplify whatever structure it enters. If processes are unclear, they scale confusion. If capability is thin, dependence deepens. The real work, then, sits upstream from the model itself (in purpose, literacy, and shared ownership), the parts that determine whether AI becomes a usable system or a faster way of reproducing the same inefficiencies.
From Data Providers to Co-Creators
Q: You’ve contributed to advisory work on digital transformation at national and regional levels. What policy gaps do you believe need urgent attention for African AI to mature responsibly?
A: One of the biggest gaps is that African countries are entering the AI era without a clear, shared framework for what “responsible” looks like in our context. We are often reacting to technologies and standards defined elsewhere, instead of setting our own terms. This shows up in three areas: data governance, linguistic inclusion, and how we negotiate partnerships with global technology powerhouses.
On data and infrastructure, we urgently need policies that treat data as strategic, not incidental. That means clear rules on ownership, access, localisation, and benefit-sharing, especially when African data is used to train global models. Without this, we risk becoming perpetual data providers and model consumers, rather than co-creators of value. The same applies to language: most digital strategies still treat African languages as a cultural issue, not as core digital infrastructure. That has to change if we want AI systems that serve the majority of our populations.
A second gap lies in how we negotiate our seat at the global AI table. Too often, partnerships with Africa are framed as “capacity building” or technology “donations,” when what we actually need are fair, co-designed arrangements: shared IP, joint research agendas, commitments to local capability and jobs, and alignment with our regulatory priorities. We need AI that is built for our own problems and development goals, not technologies deployed as sales pilots or experimental rollouts. Africa should not be a testing ground; it should be a co-author of the rules that shape AI.
The Ubuntu AI Framework and its accompanying scorecard emerged from a collaborative, multidisciplinary project that I had the privilege to contribute to. They were shaped by collective expertise - researchers, policymakers, civil society actors, and technologists working together to translate Ubuntu principles into actionable guidance for AI governance. The framework encourages institutions to ask foundational questions: Who benefits? Who is represented? Whose values guide this system?
The scorecard reflects this collective ethos. It operationalises principles such as relationality, community accountability, fairness, and inclusion into concrete criteria that can be used to evaluate policies, platforms, and partnerships. Because it was co-created, it carries a shared ethical grounding rather than the imprint of any single perspective.
In this way, the framework becomes more than a document - it becomes a strategic tool for strengthening Africa’s negotiating position. It provides governments and institutions with a common language and a robust baseline to bring into engagements with global technology companies and multilateral bodies, ensuring that African values, priorities, and communities remain central in shaping responsible AI.
Editorial commentary: Standards arrive, partnerships are proposed, infrastructure gets financed, and only later do countries discover that most of the terms were set elsewhere. By then, data has already flowed outward, languages have already been sidelined, and local institutions are positioned as implementers rather than designers. The shift she is arguing for is subtle but material: moving from participation to co-definition.
Treating data and language as strategic assets rather than cultural or technical side notes alters how negotiations are entered in the first place. Agreements begin to hinge on ownership, reciprocity, and long-term capability instead of short-term access to tools. Frameworks like the Ubuntu AI work she references operate in that space, not as symbolic gestures but as instruments that allow governments and institutions to enter partnerships with clearer terms and shared benchmarks.
What comes through Prof. Primus’s insight is less a call for protectionism than for positional clarity. Without it, countries remain sources of data and sites of deployment. With it, they gain the ability to shape how systems are built, evaluated, and governed, and to decide which forms of collaboration strengthen local capacity rather than bypass it.
Fixing Structures, Not Resilience
Q: As someone committed to women’s leadership in science and technology, what changes would you like to see to support more women entering AI and computer science?
A: I would like to see environments that make it possible for women to thrive without having to carry the burden of proving they belong. Too often, we ask women to build resilience rather than fixing the structures that make resilience a requirement. The changes we need are cultural, institutional, and practical.
Culturally, we need to normalise women’s presence in technical spaces, not as exceptions, but as contributors and leaders whose work shapes the field. Representation matters, but visibility alone is not enough; women also need room to speak, to question, and to lead without being penalised for it.
For me, supporting women in AI is not about “fixing the pipeline.” It’s about transforming the ecosystem so that women are not only welcomed into the field, but empowered to shape its future.
Editorial commentary: The refusal to treat women’s participation in AI as a question of endurance is what sits underneath Prof. Primus’s answer. The expectation that women must be resilient enough to withstand technical spaces leaves the structures that produce that strain untouched. Over time, the burden becomes individual rather than institutional, and the absence of women is misread as a pipeline issue rather than a design one.
Changing that requires altering how technical environments recognise authority, distribute voice, and define credibility. When women are expected to justify their presence before contributing, the field narrows long before recruitment statistics are counted. The shift she points to is quieter and more structural: building spaces where belonging is assumed and influence is ordinary, so that participation no longer depends on how much friction someone can absorb.
From AI Built For Africa to AI Built From Africa
Q: Looking ahead, what future do you imagine for African language technologies over the next decade and what impact do you hope your work will contribute to?
A: The next decade of African AI will revolve around three key questions: Who is represented? Where is the system situated? And what kind of future are we coding? Our ambition should be to shift from AI built for Africa to AI built from Africa, technologies grounded in our languages, ethics, and collective sense of personhood.
The future of AI on the continent is not only technical; it is philosophical and cultural. It requires systems that understand us as we are: multilingual, relational, and shaped by histories and knowledge systems that global models rarely reflect. It’s about building technologies that recognise our ways of communicating and reasoning, and that evolve with the communities they serve.
What I hope my work contributes is a foundation for this shift - scientifically, conceptually, and institutionally. Through research on African linguistic complexity, through multimodal datasets, through governance tools such as the Ubuntu AI Framework and scorecard, and through digital transformation work across the continent, I want to help build an ecosystem that sees African languages not as technical obstacles but as engines of innovation.
Ultimately, my hope is that African language technologies will help restore linguistic dignity, expand digital inclusion, and support a generation of researchers who feel confident building from our languages rather than around them. If the next decade belongs to AI, then African languages must belong to that story - fully, visibly, and on their own terms.
Editorial commentary: The horizon Prof. Primus sketches is more about origin, than it is about adoption. Over the past decade, most language technologies on the continent have arrived as imports, adapted where possible and worked around where not. The shift she points toward concerns where systems begin, whose linguistic assumptions sit at the centre, whose categories organise the data, whose intuitions shape how meaning is processed.
Building from African languages alters more than interface or accessibility. It changes who holds technical authority, who sets research agendas, and who defines what counts as a well-functioning model. Linguistic work becomes infrastructure. Governance frameworks become part of model design rather than something layered on after deployment. The result is an ecosystem where language is not a constraint to be managed but a source of structure for how systems are imagined and built.
What Prof. Primus’s contribution gestures toward is continuity: research, institutional tools, and transformation work feeding into one another so that the next generation of systems does not have to begin from a blank slate. Over time, the measure of progress will be less about how well global models accommodate African languages and more about how confidently those languages shape the systems themselves.
Closing remarks
What emerges across this conversation is a blueprint for technological sovereignty grounded in linguistic dignity.
Prof. Primus’s work reveals what gets lost when AI systems are built without the linguistic theory to understand African languages on their own terms: tonal distinctions that carry meaning, relational structures where identity emerges through interaction, social contexts that shape how communication works. The epistemic gap is that the AI was never designed to understand how these languages actually function.
The path forward involves designing from the ground up, algorithms that capture tonal systems, models that understand relational meaning-making, governance frameworks grounded in Ubuntu philosophy, policies that treat language as digital infrastructure rather than cultural artifact. This requires simultaneous intervention at every level: technical (building new architectures), institutional (training computational linguists), societal (recognizing African languages as essential to digital futures), and political (shifting from data providers to co-creators, from testing grounds to co-authors).
The vision is clear: AI built from Africa, not just for it. Technologies that recognize speakers of African languages not as edge cases to accommodate, but as sophisticated knowledge communities whose ways of thinking, communicating, and relating deserve to shape what AI becomes.
We cannot build inclusive AI without linguistic inclusion. We cannot achieve linguistic inclusion without understanding how languages actually work and we cannot understand how languages work without putting the L back in NLP. So, “If the next decade belongs to AI, then African languages must belong to that story—fully, visibly, and on their own terms,” is not an aspiration. It is a requirement because the alternative is systematic exclusion of hundreds of millions of people from digital economies, digital governance, and digital futures.
The foundation is being laid through tone-labeling algorithms, Ubuntu governance frameworks, organizational transformation that recognizes you cannot automate inefficiency, and policy advocacy for treating language as infrastructure.
What comes next depends on whether institutions, governments, and tech companies recognize what Prof. Primus has spent her career demonstrating: that African languages aren’t obstacles to be overcome. They’re sophisticated knowledge systems that, if taken seriously, could transform what AI becomes not just in Africa, but globally.
TAIS is currently self-funded and intentionally independent. Your support helps me keep spotlighting African innovators and building a stronger ecosystem.
This piece hits harder than most multilingual AI coverage because it frames the problem right. The issue goes beyond data scarcity or representation. Systems optimized for statistical plausibility over linguistic structure are fundamentally misaligned with languages where tone is definitional, where it carries meaning rather than decoration.
The "layered architecture of exclusion" section does real work. Technical barriers feed institutional choices. Institutional choices shape societal expectations. Societal expectations justify technical limitations. The cycle reinforces itself without anyone having to explicitly argue for marginalization. It just settles in as background.
Prof. Primus's "there is no NLP without the L" lands the methodological failure perfectly. Models trained on decontextualized text, stripped of tone and social cues, can generate fluent sentences while completely misunderstanding how meaning gets constructed. In languages where identity emerges through interaction, that's a fatal gap. More data won't fix it. It's baked into the architecture.
The Ubuntu governance framework section connects to something I've been chewing on. I just read about Eguale Gebreyohannes and his Tewahedo synthesis work, bridging Faustian and Yaredic civilizations through dialectical philosophy. There's a version of this where AI could pull structural parallels across traditions that have never been in conversation. Amharic, Greek, Mandarin, Arabic, Yoruba. Finding resonances across language barriers humans are genuinely bad at crossing.
The catch is who builds it. There's no such thing as a neutral builder. Whoever designs the synthesis engine bakes their assumptions into what gets indexed, how sources get weighted, which traditions count as primary. You get Eguale's problem at scale. The tool becomes the rootstock, and every other tradition becomes a branch getting grafted on.
Still worth pursuing. But it requires exactly what Prof. Primus is arguing for: redesign from multiple linguistic worldviews instead of treating current architectures as universal.
Great piece. You consistently surface work that matters while the mainstream press covers whatever got tweeted.



This piece hits harder than most multilingual AI coverage because it frames the problem right. The issue goes beyond data scarcity or representation. Systems optimized for statistical plausibility over linguistic structure are fundamentally misaligned with languages where tone is definitional, where it carries meaning rather than decoration.
The "layered architecture of exclusion" section does real work. Technical barriers feed institutional choices. Institutional choices shape societal expectations. Societal expectations justify technical limitations. The cycle reinforces itself without anyone having to explicitly argue for marginalization. It just settles in as background.
Prof. Primus's "there is no NLP without the L" lands the methodological failure perfectly. Models trained on decontextualized text, stripped of tone and social cues, can generate fluent sentences while completely misunderstanding how meaning gets constructed. In languages where identity emerges through interaction, that's a fatal gap. More data won't fix it. It's baked into the architecture.
The Ubuntu governance framework section connects to something I've been chewing on. I just read about Eguale Gebreyohannes and his Tewahedo synthesis work, bridging Faustian and Yaredic civilizations through dialectical philosophy. There's a version of this where AI could pull structural parallels across traditions that have never been in conversation. Amharic, Greek, Mandarin, Arabic, Yoruba. Finding resonances across language barriers humans are genuinely bad at crossing.
The catch is who builds it. There's no such thing as a neutral builder. Whoever designs the synthesis engine bakes their assumptions into what gets indexed, how sources get weighted, which traditions count as primary. You get Eguale's problem at scale. The tool becomes the rootstock, and every other tradition becomes a branch getting grafted on.
Still worth pursuing. But it requires exactly what Prof. Primus is arguing for: redesign from multiple linguistic worldviews instead of treating current architectures as universal.
Great piece. You consistently surface work that matters while the mainstream press covers whatever got tweeted.